What Is Progressive Disclosure, and Why Does Your AI Need It?
Your AI understood your business. Then you gave it more information, and the corrections piled up. Here is how progressive disclosure helps it read what the work actually needs.
In this article
Things started strong. You uploaded the document that explained your business, asked for a post, and got an argument you might actually publish.
So you kept going. Brand guidelines. Sales calls. The positioning work you spent weeks getting right.
Then the corrections piled up. Your voice drifted. The draft missed a detail you knew was in the files. Now the campaign is waiting while you explain your business again to the tool that was supposed to give you capacity.
If that feels familiar, I would look at how your AI reaches your knowledge before giving it more. In Marketing OS, we use progressive disclosure to connect the work to the detail it needs. Here is what that looks like, and a small change your team can test.
What is progressive disclosure in AI?
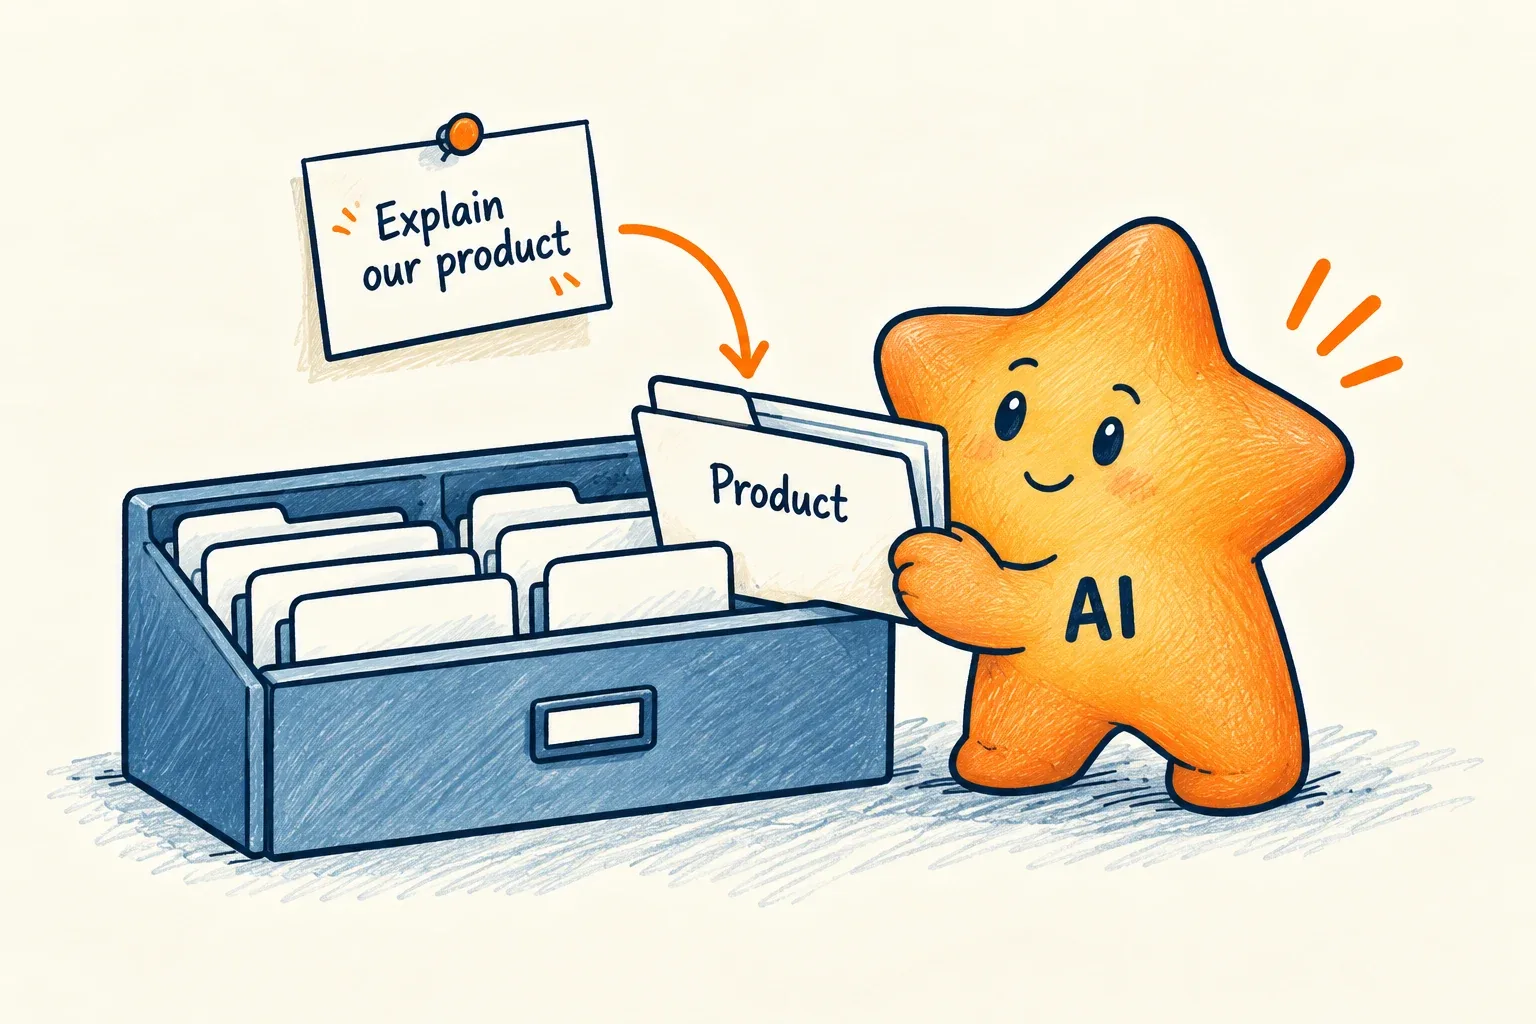
Progressive disclosure gives an AI agent essential instructions first, then directs it to more detailed information when the task calls for it. The remaining files stay available without being loaded into every request.
Keep the library. Select the next read.
Read product.md
The useful part is the connection between a need and its next source. Markdown files, links and indexes can support it. A tidy folder tree alone does not tell an agent when to read anything.
Follow one real Marketing OS reading path
Take a job your team might assign: write an article explaining what Marketing OS does for a marketing leader.
Our starting instructions point to a guide that names the messaging reading order: positioning, audience, product, differentiation, proof, then voice before drafting. Within that order, the product overview tells the agent to open the Marketing OS reference when describing that product.
The overview opens a deeper reference
- 01 / StartAGENTS.mdPoints to
core/00-positioning.md - 02 / Product stepcore/02-product.mdWhen describing Marketing OS → read its reference
- 03 / Detaillibrary/product/
marketing-os.md Buyer problems → capabilities → boundaries
The deeper file makes “structured brand knowledge” concrete: scattered documents and interviews become concise core knowledge linked to references. That gives the writer something more useful to say than “our AI knows your brand.” The detailed Conversion OS and Sales OS catalogs can stay closed unless the task needs those products too.
Later, voice guidance opens because the stage of work changes. Product knowledge answers what can we say? Voice answers how should this sound? You can inspect the need, the direction and the next layer.
Why can more information make the work harder?
The files your AI can access and the information it is using right now are different things. Its context includes instructions, conversation, retrieved documents and tool results. That working space is finite; filling it with more material can make relevant detail harder to use reliably. [1]
Your setup may load far more than the task needs. Or it may leave the useful file on disk without a good route to it. Both can leave you wondering how the draft missed something so obvious.
A bigger repository does not prove why an answer got worse. Model changes, retrieval failures and unclear instructions can also matter. Checking what was actually read gives you somewhere concrete to start.
Give your starting file a smaller job
The temptation is to put everything important at the top. Eventually the starting file becomes a record of every time AI annoyed you.
I’d keep essential business direction and rules that always apply, then route the agent to detailed methods, product catalogs and channel examples. OpenAI describes a similar approach: short agent instructions act as a map into deeper documentation. [2]
Here is a small rewrite your team can try. The filenames are illustrative; substitute your actual paths and move the detailed rules into those files.
Replace “see the library” with a reason to read
See the library for product information, channel rules and voice examples.
The agent must guess what is relevant.
Describing a product? → Read product.mdWriting a LinkedIn post? → Read channels/linkedin.md
Before drafting? → Read voice.md
Check how your tool loads files. If a link automatically imports its full destination at startup, you haven’t deferred that information. Then inspect a real run: did the agent follow the new condition and reach the file?
How long should Markdown instruction files be in 2026?
There isn’t a universal line count that makes an AI instruction file good.
Our own architecture uses targets of under 200 lines for combined entry guidance and its positioning router, and under 120 lines for each deeper core file. Those are Synapsa’s maintenance targets, not model limits or proof that a shorter file will produce a better answer.
They force a useful editorial decision: does this belong in the brief everyone starts with, or in a reference opened for a particular job?
For your team, I would use the size check this way:
- Starting instructions: retain essential direction and routes. Split when the file starts explaining several different jobs in full.
- Core guidance: keep a distilled account of one subject. Move supporting examples and source detail into linked references when they obscure that account.
- Deep references: organize for selective reading. A long reference may be justified; give it useful headings, an index or a way to retrieve the relevant section.
Count tokens as well as lines. A paragraph squeezed onto one line isn’t leaner. And a short instruction that omits a necessary distinction is just incomplete.
The useful test is whether the agent gets enough information to do the work, without loading unrelated material by default. Progressive disclosure can add retrieval steps, so it doesn’t guarantee a faster response on every task. [1]
Keep the route useful as the library grows
Direct links work for stable guidance. An index helps the agent choose among new product notes, research and examples. Its entries need to explain why a file is worth opening.
Write the description once. Rebuild the map.
Abstract: Marketing OS capabilities, buyer problems, production examples and limits.
Core tags: 02 product; 03 differentiation.
Marketing OS capabilities, buyer problems, production examples and limits.
library/product/marketing-os.mdMarketing OS library documents carry descriptions and core-topic labels. A script uses that metadata to rebuild the index and focused views. When a document changes, update its description and tags, rebuild, then check the entry and destination.
This is one of my favorite parts: the structure has a maintenance process. AI can draft a description; deterministic software can place it in the right indexes. Neither step makes a misleading description accurate. Someone still has to check it.
Start with an index at the library entrance. Add focused views when they help narrow the choice. An index that repeats the entire library has just moved the overload up a level.
Not all knowledge should carry the same weight
There is another reason to be deliberate about those routes: not all knowledge is created equal.
Your current positioning is strategic direction. A buyer call is evidence of what that buyer said. A successful campaign is an example, not permission to reuse every claim it contains.
The starting guidance should make those roles clear. Otherwise, the agent can reach a relevant document and still use it for the wrong purpose.
The same call may send marketing toward an explanation buyers need and sales toward a question to ask on the next call. The source stays the same; the job determines what the agent does with it.
This supports progressive disclosure. It doesn’t replace it. You still need to show how the agent gets from the current job to that source in the first place.
What should a CMO or CRO ask the team to show?
Pick one recurring task that keeps coming back for correction. Ask the person maintaining your AI workspace to show you the files the agent actually read, the instruction that led to each one, and the resulting draft.
Use the Marketing OS example as your test. If the draft describes capabilities vaguely, did the agent reach the detailed product reference? If it didn’t, fix the missing or ambiguous route. Repeating “be more specific” in the prompt doesn’t repair a route that never reaches the specifics.
If it did read the right reference, inspect what it did with the information. The problem may be the writing method or the review standard. Another file won’t automatically solve that either.
Ask the maintainer to open that run’s session or tool history, or its exported execution trace if the tool provides one. Look for file-read calls with paths and returned text. Record automatically injected starting instructions separately from files opened later. A model’s answer to “what did you read?” is a lead to investigate, not evidence that a read happened.
If the tool hides those records, mark the read evidence unavailable. Rerun with supported tracing enabled, or have the maintainer capture the visible tool activity. Keep the task, input and run identifier with the draft so the comparison refers to the same work.
Then give your team this inspection brief:
Use a recent task and its actual read log. Show what loaded at the start, what opened later, and why. Identify one missing necessary read or one unnecessary read. Change the route or index entry that caused it, then rerun the same task. Compare the read logs and the outputs. Check the exact issue we were correcting, and whether the change introduced a new omission.
Your team will still have to choose what belongs in the core, maintain descriptions and judge the finished work. You are making that judgment reusable instead of expressing it again in every frustrated follow-up.
That is the point for me. The business should be able to accumulate knowledge without making good work depend on an ever-longer opening prompt.
Before adding another rule, look at the first file. Then look at where it sends the AI. And the next place after that.
Frequently asked questions
Is progressive disclosure the same as organizing files into folders?
No. Folders arrange the material. Progressive disclosure controls when the agent receives it. A useful setup connects a task or stage of work to the next source, with enough description to choose correctly.
Does an index automatically make AI read a file?
No. The agent needs access to the file, a reason or instruction to consult the index, and useful entries. Test actual reads; a neat folder tree doesn’t establish that the route works.
Does progressive disclosure reduce token use?
It can reduce unnecessary context when it replaces indiscriminate loading. But retrieval and repeated reads also cost tokens and time. Compare representative runs and output quality before claiming savings.
Can I do this without Marketing OS?
Yes. The pattern can work in an agent workspace that supports file access and task instructions. Marketing OS applies it to maintained brand knowledge and the methods your marketing team uses to produce work. If you want to see that broader system, explore Marketing OS.
References
[1] Anthropic, Effective context engineering for AI agents. Guidance on finite context, selective retrieval and the trade-offs of retrieving information while working.
[2] OpenAI, Harness engineering. A short agent instruction file serving as a map into maintained documentation.